

Denormalization is a database optimization technique where redundant data is intentionally added to one or more tables to reduce the need for complex joins and improve query performance. It is not the opposite of normalization, but rather an optimization applied after normalization.
- In a normalized database, data is stored in separate tables to minimize redundancy.
- For example, storing teacher details in a Teachers table and course details in a Courses table, linked by teacherID.
- While this maintains data integrity, frequent joins between large tables can slow performance.

Above diagram illustrates denormalization in a data warehouse, where related normalized tables such as Subject, Supplier, City, Region, and Date are combined into wider dimension structures. The final Contract table stores dimension-related data together, reducing the number of joins required during querying and improving read performance.
Note: Denormalization strikes a balance by allowing some redundancy to achieve faster data retrieval and better performance, at the cost of slightly more maintenance effort when updating data.
Step 1: Unnormalized Table
This is the starting point where all the data is stored in a single table.

- Redundancy: For example, "Alice" and "Math" are repeated multiple times. Similarly, "Mr. Smith" is stored twice for the same class.
- Update Anomalies: If "Mr. Smith" changes to "Mr. Brown," we have to update multiple rows. Missing one row could lead to inconsistencies.
- Inefficient Storage: Repeated information takes up unnecessary space.
Step 2: Normalized Structure
To eliminate redundancy and avoid anomalies, we split the data into smaller, related tables. This process is called normalization. Each table now focuses on a specific aspect, such as students, classes or subjects.

- Reduced Redundancy: "Mr. Smith" is stored in one place and referenced by related records, reducing unnecessary duplication.
- Easier Updates: If "Mr. Smith" changes to "Mr. Brown," you only update the Classes Table and it automatically reflects everywhere.
- Efficient Storage: Repeated data is eliminated, saving space.
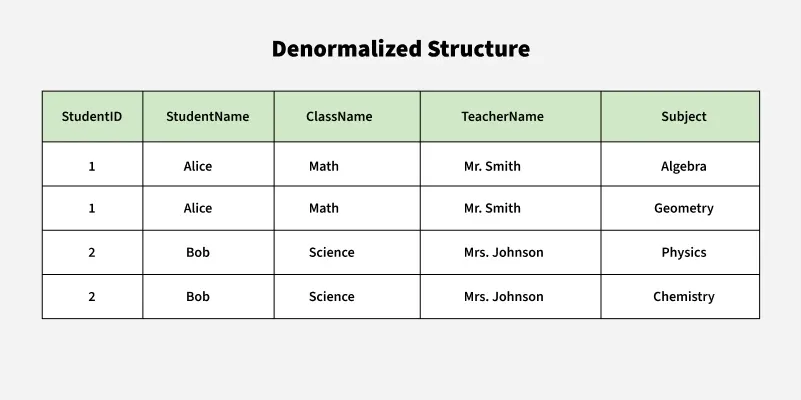
Step 3: Denormalized Table
Normalization can sometimes make queries complex and slower because retrieving data may require joins across multiple tables. To optimize specific queries, denormalization intentionally introduces controlled redundancy by combining tables, duplicating frequently accessed fields, storing precomputed values, or maintaining summary tables.
- All related information (student name, class name, teacher and subject) is stored in a single table.
- This simplifies querying because you don’t need to join multiple tables.
Denormalization v/s Normalization
Normalization organizes data into related tables to reduce unnecessary redundancy and improve data integrity. Denormalization intentionally introduces some redundancy into a normalized design to optimize specific query and read patterns, often by reducing joins or storing derived data. In practice, systems may use both normalization and denormalization depending on their workload and performance requirements.
Denormalization is used for add the redundancy into normalized table so that enhance the functionality and minimize the running time of database queries (like joins operation ) and optimizes for performance and query simplicity. In a system that demands scalability, like that of any major tech company, we almost always use elements of both normalized and denormalized databases.
Advantages
This section highlights the benefits of denormalization in improving performance and simplifying data access.
- Improved Query Performance: Denormalization can improve query performance by reducing the number of joins required to retrieve data.
- Reduced Complexity: By combining related data into fewer tables, denormalization can simplify the database schema and make it easier to manage.
- Simplified Read Queries: Denormalization can simplify read queries by storing related or frequently accessed data together, reducing the need for complex joins.
- Improved Read Performance: Denormalization can improve read performance by making it easier to access data.
- Improved Read Scalability: Denormalization can help read-heavy workloads scale by reducing joins and allowing frequently accessed data to be retrieved more efficiently.
Limitations
This section outlines the limitations of denormalization, particularly those related to data redundancy, consistency, and maintenance.
- Reduced Data Integrity: Redundant data can increase the risk of inconsistent values across the database.
- Higher Data Redundancy: The same data may be stored in multiple places, leading to duplication.
- Increased Storage Requirements: Duplicate data consumes additional storage space.
- Complex Updates and Maintenance: Changes may need to be applied in multiple locations, making updates more difficult.
- Limited Flexibility: A denormalized schema can be harder to modify when database requirements change.